TOWARDS A COMPUTATIONAL MODEL OF REALITY
4.4
Extracting Structure from the World through Pattern Recognition
Now that we have a more concrete definition of what mental representations are, we turn to a foundational question: how does the brain actually build them? One of the most influential answers comes from pattern recognition – an approach rooted in classical neuroscience and modern machine-learning that explains perception as the step-by-step extraction of increasingly complex features from sensory input.
Perception depends on constructing structured, useful mappings of the world. The question now is:
How can the visual system actually build these representations from raw sensory data?
One influential approach to answer this question is called pattern recognition. It treats perception as a process of detecting simple features and assembling them into increasingly complex structures. At every stage, the system extracts regularities – edges, orientations, shapes – and uses these to classify objects.
We can pick up with the work of Hubel and Wiesel. They discovered that early visual cortical neurons (“simple” cells) seemed to be tuned to bars at a specific orientation and location, while higher-level visual cortex neurons (“complex” cells) were tuned to orientation regardless of position. This led them to propose a hierarchical model of the visual cortex: as you move higher, the input from receptive fields of lower levels are combined to detect more complex shapes and features. This is the basis of the “pattern recognition” account of vision, a feedforward view of vision that has guided neuroscience for nearly half a century.
Inspired by this work, Japanese computer scientist Kunihiko Fukushima developed the Neocognitron (1980): a pioneering deep, layered neural network that could recognize handwritten digits.
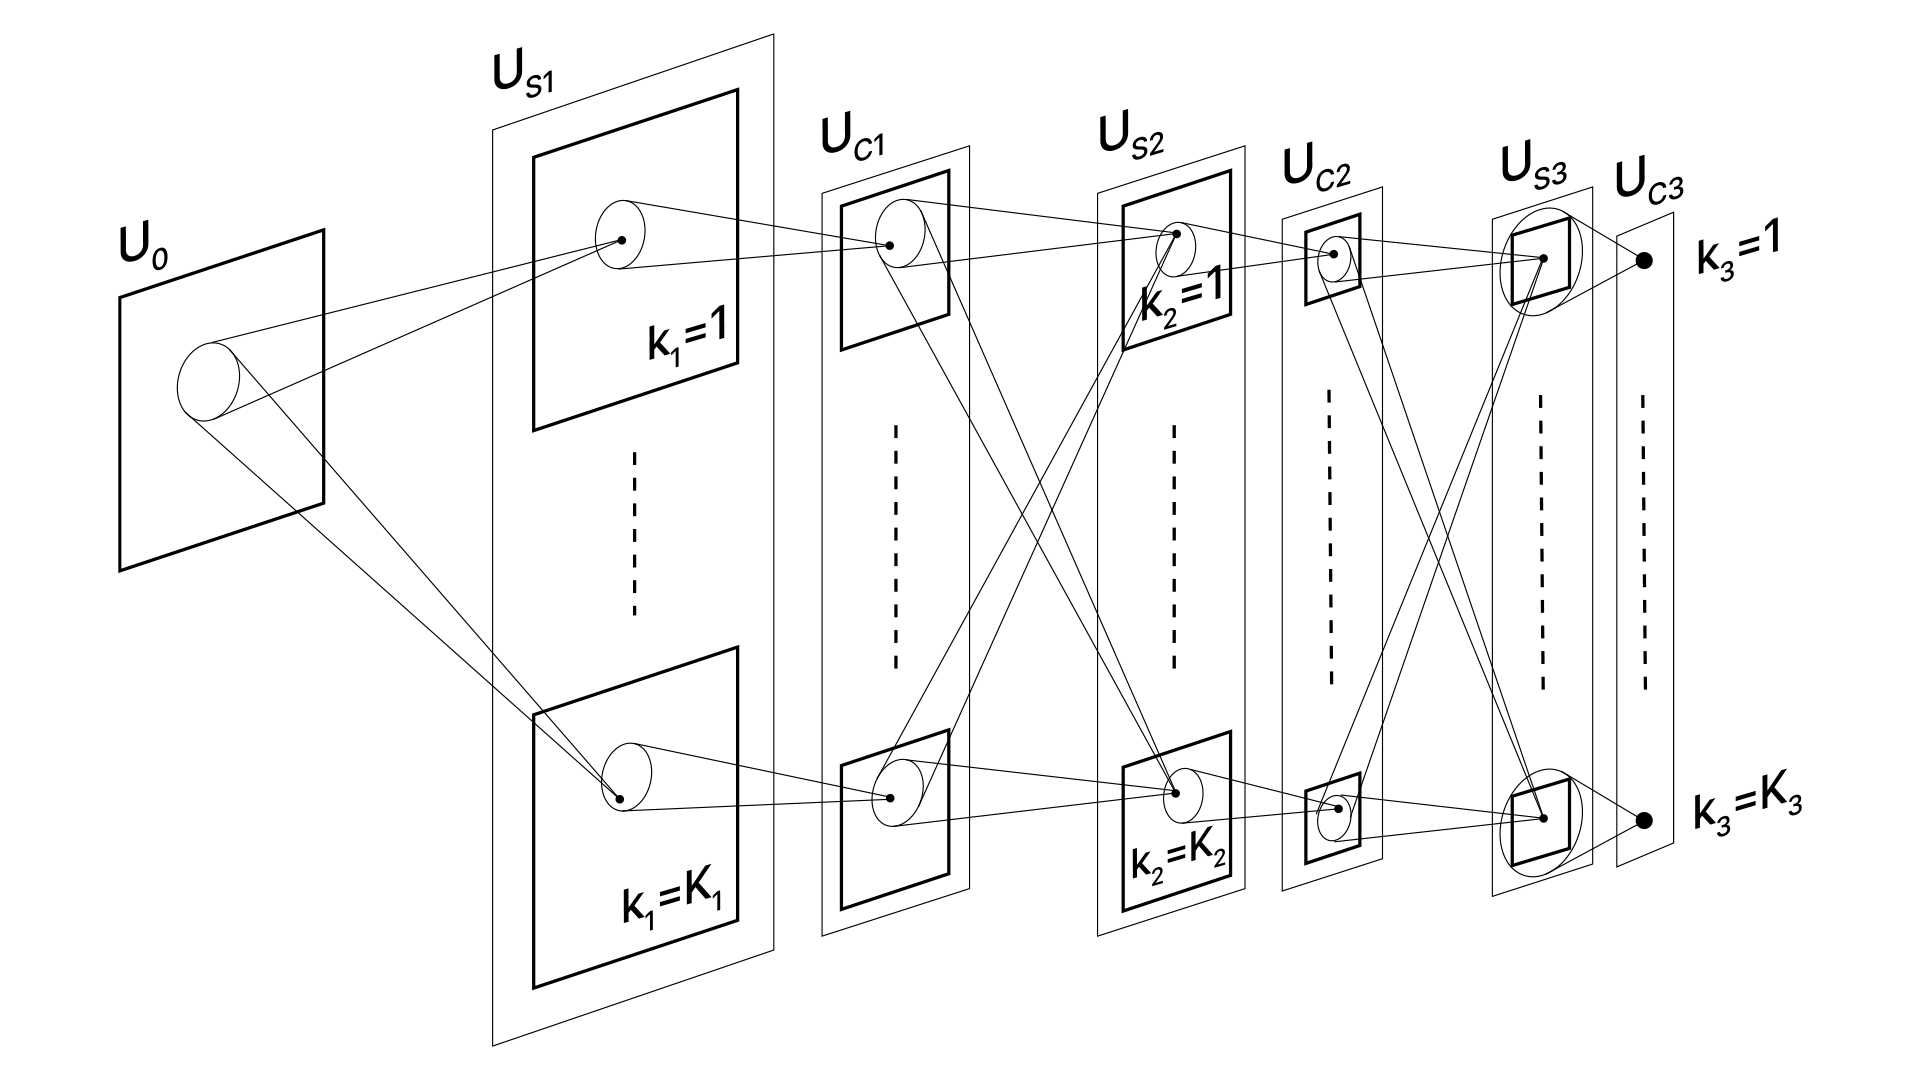
Kunihiko Fukushima (1980)
Neocognitron: a self-organizing neural network model for a mechanism of pattern recognition unaffected by shift in position.
The Neocognitron built up its understanding in stages, much like the visual cortex. Early layers identified simple features – lines and curves – at different locations in the image. Higher layers combined these into more complex parts of digits. At the top of the hierarchy, units responded to complete digits, having integrated all the feature information from below. Over time, researchers found that this architecture was a surprisingly good approximation of object recognition in the primate brain.
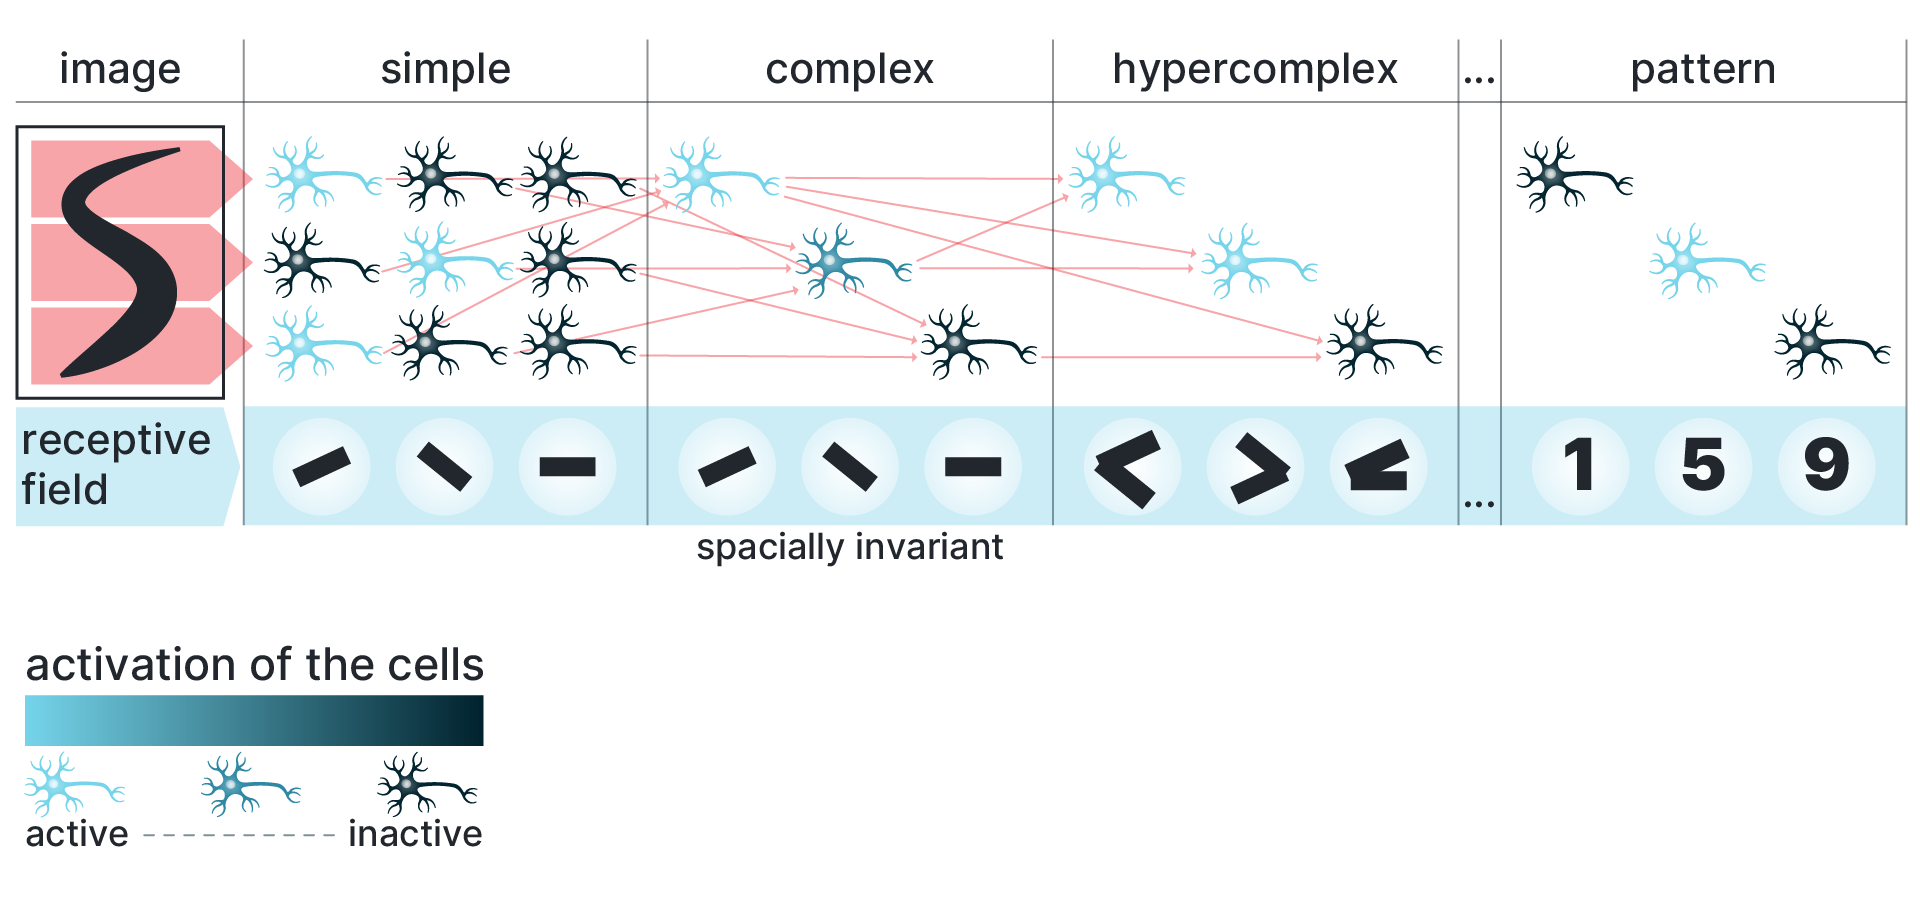
Hubel and Wiesel: Hierarchical feature selectivity in the visual cortex
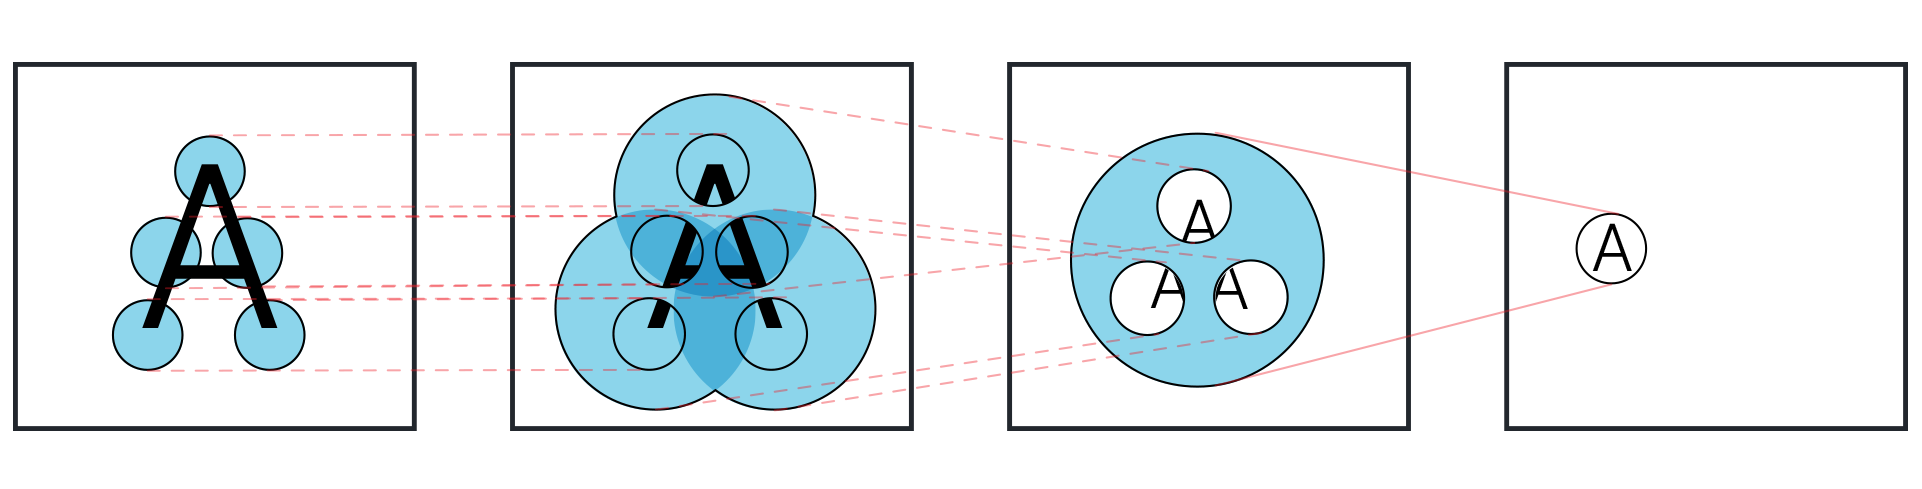
Kunihiko Fukushima: Neocognitron
Pattern Recognition
Fukushima’s Neocognitron was more than an engineering breakthrough. It laid the conceptual foundation for today’s convolutional neural networks (CNNs), which also build up complex representations by detecting simple features first and combining them across successive layers.
Here, pattern recognition refers to classifying an input by identifying the visual features and spatial patterns associated with a particular category. For example, the system learns the patterns that distinguish the letter “A,” allowing it to classify different images as instances of an “A” despite variations in handwriting or position.
If you’re curious about the logic behind these architectures, you may find the following YouTube video helpful: Convolutional Neural Networks Explained (CNN Visualized).
But what about more complex images? A classic machine-learning task is distinguishing cats from dogs.
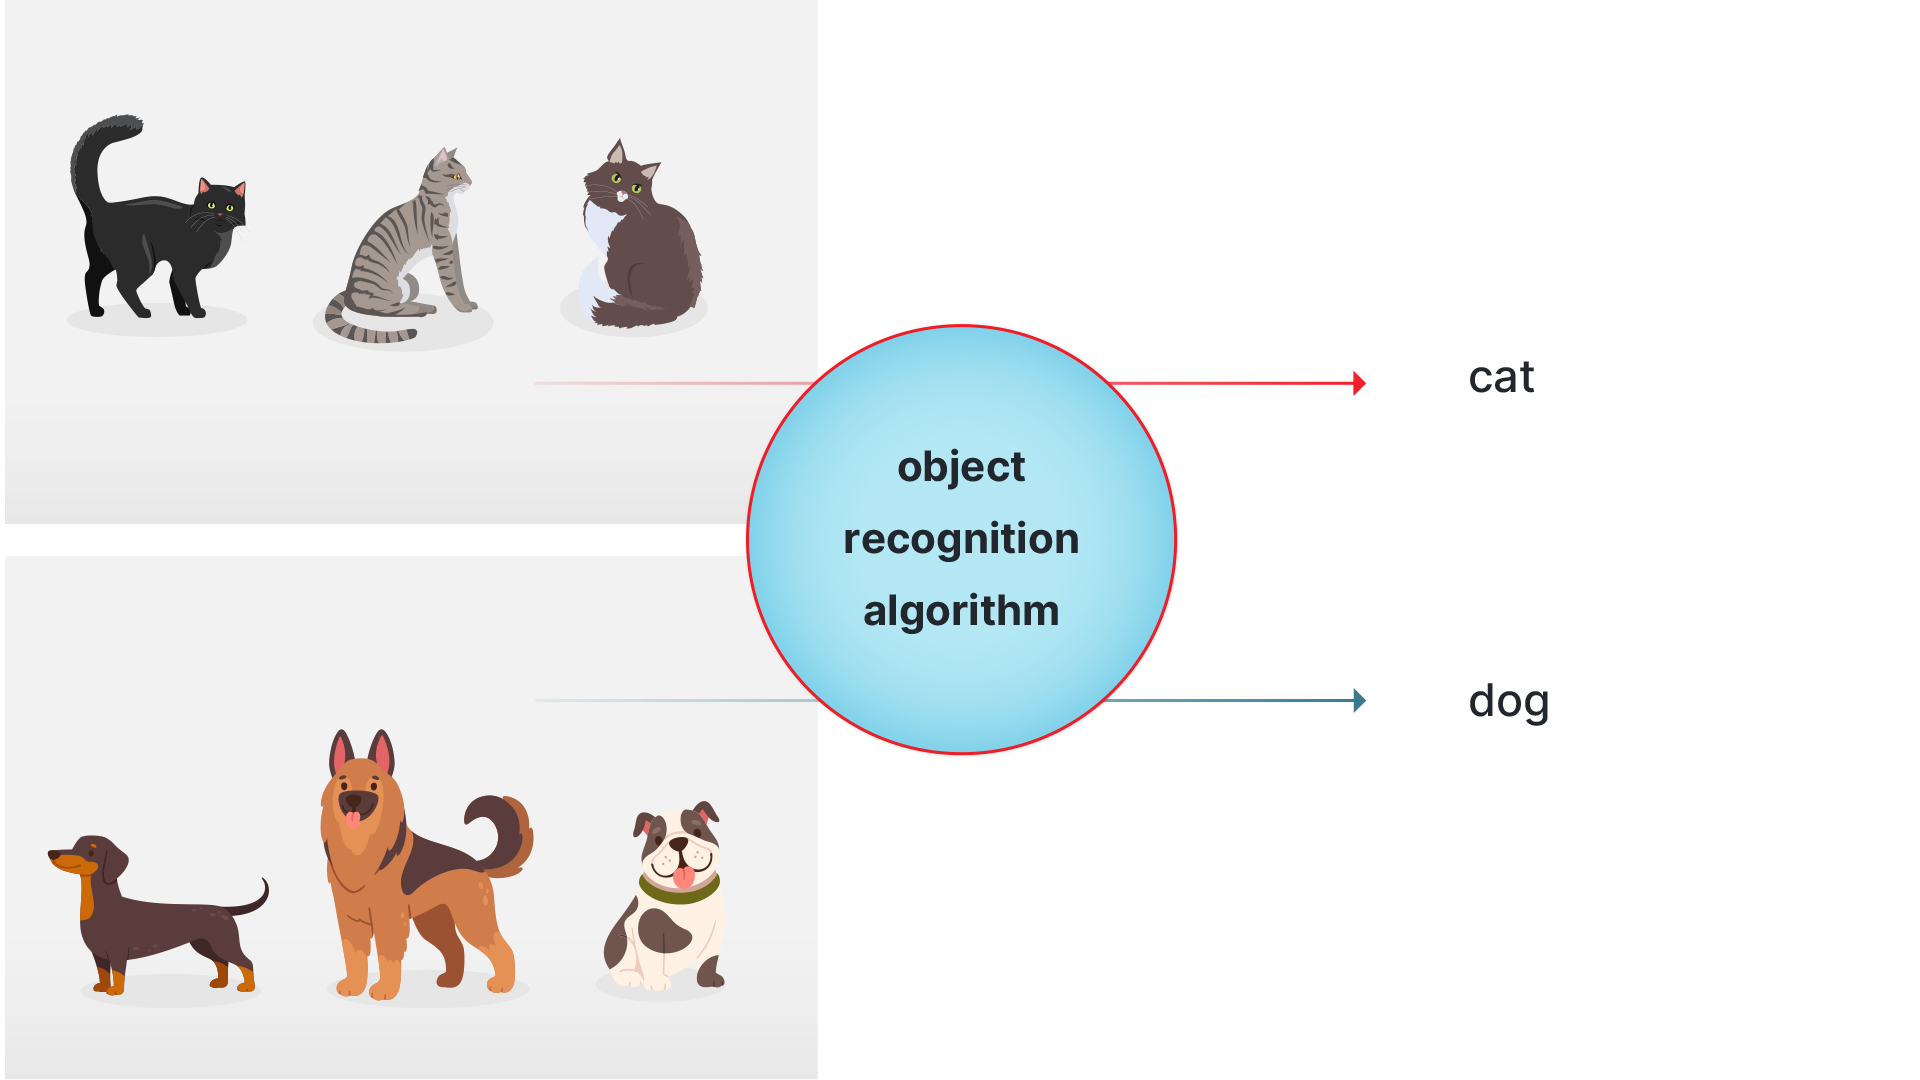 Object recognition as a classification task. Images of cats or dogs, varying in breed, posture, and viewpoint, are mapped to a category label (cat or dog) by an object recognition algorithm. In the feedforward system illustrated here, information flows in one direction, from the image through successive processing stages to a category label, with each stage extracting progressively more complex features.
However, the feedforward pattern-recognition account described here assumes that sensory input is processed bottom-up through successive layers. Because the same retinal image can arise from different physical scenes, sensory input alone cannot always uniquely determine its cause. In such cases, bottom-up processing alone is not enough.
Authors: Fabian Mueller & William Palmer